CoSQL: A Conversational Text-to-SQL Challenge Towards Cross-Domain Natural Language Interfaces to Databases
We present CoSQL, a corpus for building cross-domain, general-purpose database (DB) querying dialogue systems. It consists of 30k+ turns plus 10k+ annotated SQL queries, obtained from a Wizard-of-Oz (WOZ) collection of 3k dialogues querying 200 complex DBs spanning 138 domains. Each dialogue simulates a real-world DB query scenario with a crowd worker as a user exploring the DB and a SQL expert retrieving answers with SQL, clarifying ambiguous questions, or otherwise informing of unanswerable questions. When user questions are answerable by SQL, the expert describes the SQL and execution results to the user, hence maintaining a natural interaction flow. CoSQL introduces new challenges compared to existing task-oriented dialogue datasets: (1) the dialogue states are grounded in SQL, a domain-independent executable representation, instead of domain-specific slotvalue pairs, and (2) because testing is done on unseen databases, success requires generalizing to new domains. CoSQL includes three tasks: SQL-grounded dialogue state tracking, response generation from query results, and user dialogue act prediction. We evaluate a set of strong baselines for each task and show that CoSQL presents significant challenges for future research.
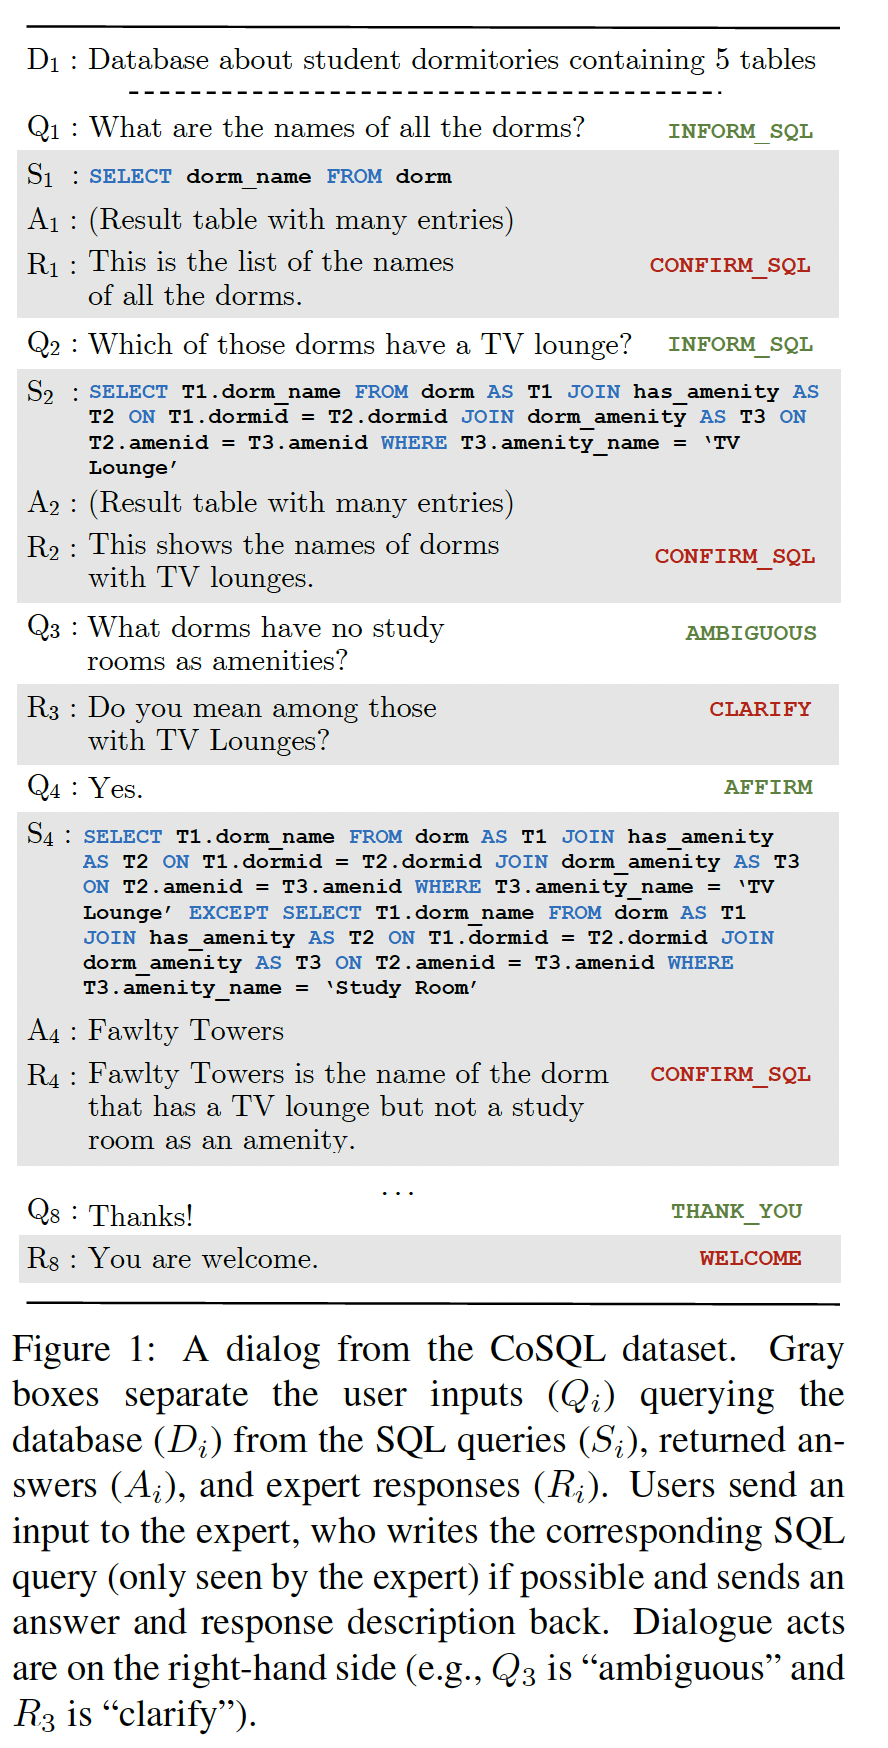
Introduction. Natural language interfaces to databases (NLIDB) have been studied extensively, with a multitude of different approaches introduced over the past few decades. To this end, considerable progress has been made in querying data via natural language (NL). However, most NL query systems expect the Wang et al., 2018; Yu et al., 2018b,c). In reality, complex questions are usually answered through interactive exchanges (Figure 1). Even for simple queries, people tend to explore the database by asking multiple basic, interrelated questions (Hale, 2006; Levy, 2008; Frank, 2013; Iyyer et al., 2017). This requires systems capable of sequentially processing conversational requests to access information in relational databases. To drive the progress of building a context-dependent NL query system, corpora such as ATIS (Hemphill et al., 1990; Dahl et al., 1994) and SParC (Yu et al., 2019)1 have been released. However, these corpora assume all user questions can be mapped into SQL queries and do not include system responses.
Discussion / Conclusion. In this paper, we introduce CoSQL, the first large-scale cross-domain conversational text-to- SQL corpus collected under a Wizard-of-Oz setup. Its language and discourse diversity and crossdomain setting raise exciting open problems for future research. Especially, the baseline model performances on the three challenge tasks suggest plenty space for improvement. The data and challenge leaderboard will be publicly available at https://yale-lily.github.io/ cosql. Future Work As discussed in Section 5, some examples in CoSQL include ambiguous and unanswerable user questions and we do not study how a system can effectively clarify those questions or guide the user to ask questions that are answerable. Also, some user questions cannot be answered with SQL but by other forms of logical reasoning the correct answer can be derived.
Lines of inquiry this paper opens 24
Research framings built by reading the notes related to this paper — the questions it feeds into.
Can language models reliably simulate personas and predict behavior? Which reinforcement learning modifications most improve dialogue quality in language models? What makes process supervision effective for training complex reasoning models? What capabilities differentiate diffusion from autoregressive language models?- Can autoregressive models learn faithful translation to logical representations without semantic loss?
- Why do hybrid paradigms outperform pure autoregressive or pure diffusion approaches?
- How do general language model benchmarks predict specialized domain performance?
- Do standard language benchmarks underestimate what LLMs can actually do?
- Do LLMs need world models to make accurate predictions?
- Do monolithic prompts underutilize LLM strengths in forecasting workflows?
- How should organizations redesign workflows if LLMs cannot solve optimization directly?
- Can a model be strong at MMLU but weak at long-horizon tasks?
- How should benchmarks evaluate workflow architecture versus raw model performance?
- Why do macro and micro forecasting scales require different reasoning approaches?
- How do search and reasoning workflows improve forecasting performance over base models?
- What real-world forecasting domains benefit most from contextual reasoning integration?
- Do newer language model generations improve forecasting ability without additional training?
- Why do non-experts default to familiar chart types despite domain complexity?