A Survey on Concept Drift Adaptation
 “Our digital universe is rapidly growing. The volume of data generated in 2012 has been estimated to surpass 2:8 zetabytes (2:8 trillion gigabytes) as reported in the IDC survey [Gantz and Reinsel 2012]. Efficient and effective tools and analysis methods for dealing with the ever-growing amount of data in different applications and fields are of paramount need. Traditionally in data mining already collected data is processed in an offline mode. For instance, predictive models are trained using historical data given as a set of pairs (input, output). Models trained in such a way can be afterwards applied for predicting the output for new unseen input data. However, very often data comes in the form of streams. Accommodating large volumes of streaming data in the machine’s main memory is impractical and often infeasible. Hence, only an online processing is suitable. In this case, predictive models can be trained either incrementally by continuous update or by retraining using recent batches of data. But computational efficiency is not the only issue in supervising learning from data streams.
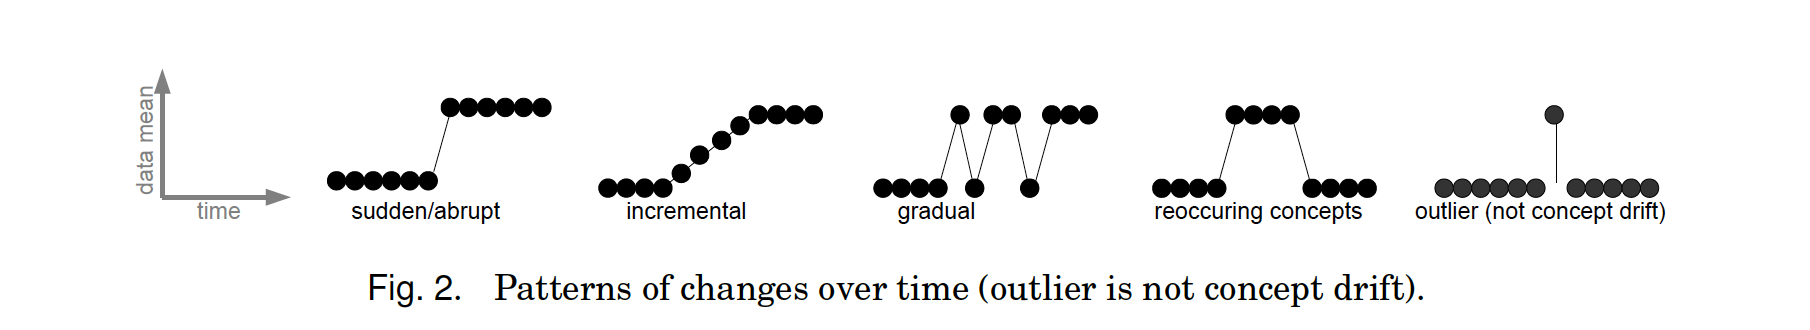
In dynamically changing and non-stationary environments, the data distribution can change over time yielding the phenomenon of concept drift [Schlimmer and Granger 1986; Widmer and Kubat 1996]. The real concept drift refers to changes in the conditional distribution of the output (i.e., target variable) given the input (input features), while the distribution of the input may stay unchanged. A typical example of the real concept drift is a change in user’s interests when following an online news stream. Whilst the distribution of the incoming news documents often remains the same, the conditional distribution of the interesting (and thus not interesting) news documents for that user changes. Adaptive learning refers to updating predictive models online during their operation to react to concept drifts.”
Lines of inquiry this paper opens 18
Research framings built by reading the notes related to this paper — the questions it feeds into.
How should recommendation systems balance individual preference and diversity?- What architectural choices support per-user concept drift in recommendation models?
- How should recommendation systems balance individual preference signals with population-level patterns?
- Why do standard accuracy metrics fail to catch diversity collapse in recommenders?
- Why do too-dynamic recommendations confuse users during active sessions?
- Should recommenders discard old user data uniformly or selectively retain historical signals?
- Can in-session recommendation and long-horizon per-user drift be modeled in the same framework?
- Why do shared accounts create heterogeneous preference drift within single user profiles?
- How can recommendation models handle per-user concept drift instead of global drift?
- Why do standard preference alignment methods fail at the individual user level?
- How do per-user concept drift and per-period periodicity combine in time-varying preferences?
- Why do conversational queries drift away from what triggered them?
- How does conversation drift from original goals affect user satisfaction?